 Two Hands
What I measured, and where it breaks
Every number on this site, with its method and source. The headline run is a pre-registered random sample of 300 forms: sample, prompt, gate and metrics were committed before any model read. Report (PDF)
- 52capture errors found in 6,358 fields of 289 random forms, each settled on the photo
- 91.6% vs 62.84%field match on Baja California Sur's 2024 local actas, vs the Google Document AI reading the state bought (same metric)
- 27 of 28certified-detectable capture errors caught (Colima, pre-registered; not total recall)
- 1 in 605fields wrong on the 18% of forms the gate accepted with no person (1 in 37 for the model alone)
- $0.14measured AMD compute per 1,000 forms
Findings: every capture error of the random 300, with its photo · The sample audit
On this page: Random 300 · Colima · Head-to-head · Gate tiers · Readers on AMD · Limitations · Cost and buyer · Any form · All runs · Evolus · AMD status · Execution trace
Pre-registered random run: 300 forms
Gemma-4-31B-IT on AMD, frozen prompt and gate. Graded against the official two-person capture (PREP) on the 22 fields it keys; every disagreement settled on the photo.
| Forms | 300 drawn; 289 located and read; 11 routed to a person before any model call |
| Fields compared | 6,358; the model agrees with the capture on 6,091 (95.8%), disputes 267 (4.2%) on 104 forms |
| The 267 disputes, settled on the photo | capture does not match the paper 52 · model misread 156 · both off 17 · paper ambiguous 34 · unreadable 8 |
| The model alone | wrong on 173 of 6,358 fields, about 1 in 37 |
| Accepted at second capture | 55 of 300 forms (18%; 27 phone photos, 28 scans); 2 of 1,210 fields wrong, about 1 in 605 (Wilson 95% 0.04% to 0.60%) |
| Capture errors found | 52 on 26 forms; the certified count covers 31 and confirms the image on 22; all 9 differences were recounts |
| Yield | 1 in 5 disputed fields is a confirmed capture error; the capture's overall error rate is at least 1 in 122 |
| Recall | On the forms the certified count settled by comparison, it differs from the first capture on 23 fields; judged on the paper, 16 of them are council corrections or blank rows (the paper shows the capture's value), and the model disputed 7 of the other 7: 1 a confirmed capture error, 6 where the paper is ambiguous. On these forms recall on confirmed capture errors rests on 1 field, too few to measure; the measured recall is the Colima check. Before judging the paper: 7 of 23 (Wilson 95% 16% to 51%), a loose lower bound. |
| Second reader (Qwen3.8-27B) | Qwen3.8-27B read the same pages (239 usable reads of 300 forms). Alone, the frozen gate accepted 31 of its reads (10%): 1 of 682 accepted fields wrong, 2 undecided on the paper. With two readers (strict mode, Amendment 2: Gemma and Qwen agree on all 23 digits, the words agree with them and the vote rows sum to the total): 89 forms (30%), 0 of 1,958 accepted fields wrong; the 3 accepted fields where they differ from the official capture are all capture errors. |
Business reading, known limitation, and sources
Business result. On 289 random forms already keyed twice, the model sent 267 of 6,358 fields (4.2%) to a person, and 52 of those were fields where the official capture does not match the paper, each with its photo: 17 wrong numbers typed; 27 readable fields recorded as illegible, 23 of them on two faint pencil forms; 6 numbers typed where the paper is blank; 2 other. Each with its photo. Alone, one model mis-keys 1 field in 37. Two models that agree, refereed by the paper, mis-keyed 0 of 1,958 accepted fields against the official capture. Cost $0.000144 per form on AMD, so $0.14 per 1,000 forms.
Known limitation: one reader, one adjudicator, and recall measured on one state. Every disagreement was settled from the photo by the AI adjudicator (the builder's model, which could see both values) on published crops, which anyone can re-check; a blind spot-check page lets a person do so without seeing any AI or capture value. Only disagreements were checked, so errors the model shares with the capture are not counted; fields where the model and the capture agree were not individually checked (a blind check of a random 200 is at /check?set=agree200). Recall on the capture errors the certified count reveals, Colima (pre-registered, a person's blind check): 27 of 28 caught, 96% (Wilson 95% 82-99%). One state, certified-detectable errors only; not total recall. The multiple between 1 in 5 and 1 in 122 depends on recall on the random 300, which was not measured there; up to 24 times if the model finds nearly every error. My pacing on a shared key reads about 2 forms a minute; a national run needs a dedicated AMD endpoint.
sourceresults/calls_gemma.jsonl (last read per form), results/adjudication/SUMMARY.md, CERTIFIED.md, RECALL.md, verdicts.json; summarised in app/data/headline.json by scripts/build_headline.py Sources: results/calls_gemma.jsonl and results/adjudication/. A post-hoc gate variant designed after seeing these reads is reported separately in results/posthoc_v2_300.md and is not a test of anything.
Colima, the whole state
Pre-registered in PROTOCOL.md Amendment 8b before any Colima read: every presidential sheet of one state, Gemma-4-31B-IT on AMD Token Factory, the same frozen prompt and gates as the 300, one read per form, graded against the first capture (PREP).
One reader, frozen gate: 2 wrong of 1,210 accepted fields on 300 random forms (0.17%), 13 of 8,382 on a whole state (0.16%).
| Forms | 1,017 presidential sheets in the PREP; 982 located and read by Gemma-4-31B-IT on AMD Token Factory, one request each, $0.14 in all; 35 not located, listed. The 35060070C0100, 060071B0100, 060139E0204, 060152E0100, 060152E0102, 060156C0100, 060159B0100, 060162C0100, 060176B0100, 060177B0100, 060177C0100, 060202C0100, 060203B0100, 060206C0200, 060213B0100, 060221C0100, 060226B0100, 060230E0100, 060234C0300, 060236E0304, 060239B0100, 060250C0400, 060250E0102, 060260B0100, 060260C0100, 060289B0100, 060290C0300, 060291B0100, 060321B0100, 060326B0100, 060337C0100, 060378C0200, 060384C0200, 060385B0100, 060397C0100 |
| Accepted with no person | Frozen gate (v1, primary): 381 accepted with no person (37.5% of 1,017), 13 wrong of 8,382 accepted fields (Wilson 95% 0.09% to 0.27%). Wrong by the AI adjudicator's reading of the masked crops. |
| Who decided the 13 | Each of the 13: AI adjudicator's reading (it sided with the capture against Gemma); checked by a person: 12 of 13 agree. 9 of the 13 are unused ballots, the one field outside every identity; the other 4 (2 ballots taken from the boxes, 1 TOTAL, 1 Option 05) sit inside an identity and passed because the read kept every identity true (a compensating or harmonised read, as in the 239/239 case): the gate's blind spot made visible. |
| Disputes | 510 disputes with the first capture: 96 settled by the certified count (in 27 of them the capture does not match the paper); 333 AI adjudicator's reading; 81 paper ambiguous; 0 awaiting review. The accepted-field error rate is complete, and every dispute carries a label. |
| Phone photos and scans | Colima accepts 37.5% of forms, against 18% on the national random 300; phone photos pass about as often as scans (39.3% and 37.6%), and scans carry 11 of the 13 accepted errors. |
| Missed capture errors | Recall on capture errors the certified count sees (Amendment 9, a person's blind check): 27 caught, 1 missed, 96.4% (Wilson 95% 82.3% to 99.4%); of the 139 fields where Gemma agreed with a capture the certified count changes, 1 are capture errors Gemma also missed, 95 later corrections by the council, 43 ambiguous. |
| Gate | Accepted (of 1,017) | Phone / scan | Accepted fields | Wrong (Wilson 95%) |
|---|---|---|---|---|
| v1, frozen gate (primary) | 381 (37.5%) | 267 / 114 | 8,382 | 13 (0.09% to 0.27%) |
| v2 (Amendment 3) | 344 (33.8%) | 247 / 97 | 7,568 | 7 (0.04% to 0.19%) |
| v3 (Amendment 7) | 388 (38.2%); unused ballots to a person on all 388 | 272 / 116 | 8,148 | 4 (0.02% to 0.13%) |
Full field-level report (HTML) CSV · blind person check of the 13
The gate tiers, the 13 accepted fields that differ from the paper, and sources
v1 is the primary (the headline rule); v2 and v3 are pre-registered in Amendment 8b and shown beside it. The two-reader tier was not run on Colima (single reader); 0 of 1,958 remains a 300-form result.
- 060058B0100 · Unused ballots: Gemma read 268, capture 208, paper 208 (AI adjudicator's reading)
- 060111B0100 · Unused ballots: Gemma read 29, capture 291, paper 291 (AI adjudicator's reading)
- 060151B0100 · Unused ballots: Gemma read 227, capture 229, paper 229 (AI adjudicator's reading)
- 060239C0100 · Unused ballots: Gemma read 47, capture 247, paper 247 (AI adjudicator's reading)
- 060242B0100 · Unused ballots: Gemma read 30, capture 307, paper 307 (AI adjudicator's reading)
- 060248E0208 · Unused ballots: Gemma read 44, capture 344, paper 344 (AI adjudicator's reading)
- 060248E0208 · Ballots taken from the boxes: Gemma read 381, capture 384, paper 384 (AI adjudicator's reading)
- 060248E0208 · TOTAL: Gemma read 381, capture 384, paper 384 (AI adjudicator's reading)
- 060290C0400 · Unused ballots: Gemma read 369, capture 364, paper 364 (AI adjudicator's reading)
- 060290C0400 · Option 05: Gemma read 10, capture 16, paper 16 (AI adjudicator's reading)
- 060291C0400 · Unused ballots: Gemma read 301, capture 387, paper 387 (AI adjudicator's reading)
- 060369C0100 · Ballots taken from the boxes: Gemma read 294, capture 291, paper 291 (AI adjudicator's reading)
- 060374B0100 · Unused ballots: Gemma read 79, capture 179, paper 179 (AI adjudicator's reading)
colima_audit.md · adjudication sheet · sourceresults/colima/colima_audit.json and .md (scripts/gemma_tf_reads2.py score-colima, no model call), results/colima/calls_gemma.jsonl (cost), results/colima/audit_report.html (fingerprint 511a71e9ec1f31ce); sentences in app/colima.py, checked by score-colima --check (make eval)
Head-to-head on the buyer's own actas
Baja California Sur, 2024 PREP: their first capture (commercial cloud OCR) against an open model on AMD, pre-registered in PROTOCOL_IEEBCS.md.
Strict per-field match 91.58% (3,317 of 3,622 numeric fields on all 300 actas, Token Factory, Gemma-4-31B-IT; Wilson 95% 90.63-92.44%); 93.25% on the 294 pages the locator accepted. Theirs: 62.84% (14,501 of 23,077, IEEBCS, Informe final del PREP PELO 2023-2024, p. 19).
Same images; reference and pipeline differ (their raw manual capture vs. the published values; election night vs. offline); their per-field output isn't published, so it can't be re-scored. Details on Results.
Source: results/ieebcs/score.json by scripts/ieebcs_score.py, recomputed by make eval; results/ieebcs_head_to_head.md.
Every gate tier, one table
The same 300 forms under every gate I ran. Gemma full gate is the pre-registered primary; the light gate (c) and two readers (d) were pre-registered in Amendment 2, before any Qwen read and before any adjudication. Rows marked post-hoc were designed after seeing these reads and test nothing.
| Tier | Readers | Accepted at second capture | Accepted fields wrong on the paper | |
|---|---|---|---|---|
| Gemma, full gate (primary) full: words, rows, sections, row labels |
one | 55 of 300 (18%) | 2 in 1,210 (0.17%) | primary |
| Gemma, light gate (Amendment 2 c) light: words = digits, rows = TOTAL |
one | 143 of 300 (48%) | 14 in 3,146 (0.45%); 6 undecided on the paper | pre-registered |
| Qwen, full gate full |
one | 31 of 300 (10%) | 1 in 682 (0.15%); 2 undecided on the paper | pre-registered |
| Two readers, light gate (Amendment 2 d) light, both readers agree on all 23 digits |
two | 89 of 300 (30%) | 0 in 1,958 (0.00%) | pre-registered |
| Two readers, both full gates full on both, same digits |
two | 22 of 300 (7%) | 0 in 484 (0.00%) | pre-registered |
| Gate v2 post-hoc |
one | 47 of 300 (16%) | 1 in 1,034 (0.10%) | post-hoc |
| Gate v2b (relaxed label) post-hoc |
one | 62 of 300 (21%) | 1 in 1,364 (0.07%) | post-hoc |
| Gate v2-2R (unused ballots confirmed by words or Qwen) post-hoc |
two | 54 of 300 (18%) | 1 in 1,188 (0.08%) | post-hoc |
| Gate v2-2R strict (only if Qwen agrees) post-hoc |
two | 45 of 300 (15%) | 0 in 990 (0.00%) | post-hoc |
| Fresh 100 forms (pre-registered confirmation, Amendment 3; gate v3, Amendment 7). Different forms, so different denominators. | ||||
| Gemma, gate v2, fresh 100 the fix, tested on forms drawn after it was designed |
Gemma | 22 of 100 | 0 in 484 (Wilson upper bound 0.79%) | pre-registered |
| Gemma, gate v3, fresh 100 words + two reads + ballot stock |
Gemma (no second reader run) | 24 of 100 (0 touchless) | v3 on the 100: 0 wrong of 504 accepted; with no second reader in this run every SOBRANTES went to a person, so the full v3 test waits for the 3,000 with Qwen. | pre-registered |
| Gemma, gate v2, both sets pooled 1,034 fields from the 300 (post-hoc re-score, 68% of the pool) + 484 from the fresh 100 (pre-registered) |
Gemma | 47 of 300 + 22 of 100 | 1 in 1,518 | 68% post-hoc |
Dropping the section checks takes one reader from 55 to 143 forms accepted at second capture (2.6 times as many), but errors rise to 14 in 3,146 fields (0.45%): the bookkeeping identities catch real misreads, not only inconsistent paper. With two readers the lighter gate is safe (0 in 1,958); with one reader it is not. Either way the paper decides, and every tier is published.
The fresh 100 forms, the light gate, and sources
Confirmation on fresh data (Amendment 3, pre-registered before any read): 100 forms drawn after the fix was designed, Gemma on the AMD Token Factory. The fixed gate (v2) accepted 22 forms; 0 of their 484 fields were wrong against the official capture, with 3 disagreements adjudicated from crops and checked by a person. The pre-registered criterion was an error rate under 0.5%; the point estimate meets it, and the sample is too small to exclude 0.5% at 95% confidence (Wilson upper bound 0.79%). Evidence for v2 across both sets: 1 wrong field in 1,518 accepted, of which 1,034 are a post-hoc re-score of the 300 and 484 are this pre-registered run.
On the same 100 forms the original gate would have accepted one wrong field: the model read 3114 where the paper says 314, a digit inserted. The v2 rule "a field in no identity needs its digits and words both read and equal" (Amendment 3, condition 2(a); here the words line was blank) blocked it. That is the held-out test of a rule designed after the first run, and it passed.
sourceresults/confirm100.md (scripts/confirm100_score.py; crops and AI-adjudicated verdicts in results/adjudication_confirm100/), results/posthoc_v2_300.md, recomputed by make eval; the person check of the disagreement crops: /check?set=confirm100 (app/state/spotcheck_confirm100.json)
Two readers, light gate: Gemma and Qwen read the same digits on all 23 fields, every digit field is read, the words either reader wrote down agree with those digits, and the vote rows sum to the total. It drops the row-label check and the section identities and relies on the two readers' agreement instead. The two readers agree on all 23 digits on 147 forms.
sourceresults/calls_gemma.jsonl, results/calls_qwen.jsonl (last read per form), results/adjudication/verdicts.json; app/data/two_reader_300.json by scripts/two_reader_300.py; results/posthoc_v2_300.json; both recomputed by make eval
Gemma vs the other readers on AMD
Same pre-registered forms, same frozen prompt, same gate; every reader on AMD Token Factory.
Same 300 forms, same gate, on AMD: Gemma accepts 1.8x the forms Qwen3.8-27B does at the same error rate, 4.6x cheaper and 2.8x faster, with no truncated answers. Every zero-error two-reader pair includes Gemma; the only pair without it made errors (2 of 814).
| Reader | Forms accepted | Wrong of accepted fields | $ per 1,000 forms | Mean time per read |
|---|---|---|---|---|
| Gemma-4-31B-IT | 55 of 300 (18%) | 2 of 1,210 | $0.14 | 87 s |
| Qwen3.8-27B | 31 of 300 (10%) | 1 of 682 (+2 undecided) | $0.64 | 241 s |
| Qwen3.8-Flash-Next | 17 of 128 (13%) | 0 of 374 (+1 undecided) | $2.11 | 120 s |
| Gemma-4-31B-IT + Qwen3.8-27B | 89 of 300 (30%) | 0 of 1,958 | $0.78 | – |
| Gemma-4-31B-IT + Qwen3.8-Flash-Next | 42 of 128 (33%) | 0 of 924 | $2.25 | – |
| Qwen3.8-27B + Qwen3.8-Flash-Next | 37 of 128 (29%) | 2 of 814 (+1 undecided) | $2.75 | – |
Method, the misreads the arithmetic caught, and sources
Pairs: all 23 digits agree, lighter gate (secondary). Qwen3.8-Flash-Next: first 128 forms (budget rule). Source: app/data/bakeoff_300.json.
Two Gemma reads as the two readers: 5 wrong of 2,816 accepted fields, against 0 of 1,958 with Qwen as the second reader. Same-model reads share mistakes, which is why the second reader is a different model. results/gemma_b4_300.json (PROTOCOL.md Amendment 8).
Misreads the arithmetic caught
Gemma read the digits and the words the same wrong way, so only the form's sums could catch it; the failed sum was the only reason the gate refused the form.
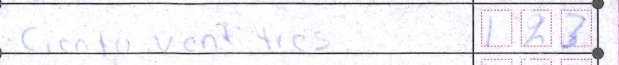
Form 122655C0100, Option 02: Gemma read 23 in the digits and 23 in the words; the paper says 123 (the official capture keyed 123, the certified count says 123). The gate refused the form: rows sum to TOTAL, 366 ≠ 466; with the paper's 123 it is 466 = 466.
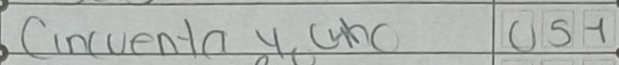
Form 110922C0100, Option 04: Gemma read 54 in the digits and 54 in the words; the paper says 51 (the official capture keyed 51, the certified count says 51). The gate refused the form: rows sum to TOTAL, 329 ≠ 326; with the paper's 51 it is 326 = 326.
Gemma-4-31B-IT reads each field twice, the handwritten digits and the amount written in Spanish words, plus the printed label of each row, on phone photos and faint pencil. It gets a fixed ~263 tokens per image whatever the resolution, so each request is the page plus 6 zoomed tiles (the vote rows at ~8x the page's token density); on rainfall ledgers that took Gemma from 79% to 97% of cells right. Frozen prompt 3664253035b9…; the first complete JSON is parsed, a reply cut at max_tokens is never accepted.
Live reads use Gemma when it is listed, and fall back to Qwen3.8-27B otherwise; every receipt names its reader. Every measured read of the 300 run is Gemma on AMD GPUs.
Which open model on AMD reads handwriting best, and which pair is the safest second keyer
Every vision model on AMD Token Factory that accepts the 7-image request, on the same pre-registered forms, the same frozen prompt 3664253035b9…, temperature 0, the same gate (Amendment 6, a secondary analysis). Refereed by the paper: accepted-field errors are judged on the crops.
Gemma-4-31B-IT is in both zero-error two-reader pairs (0 wrong of 1,958 with Qwen3.8-27B; 0 wrong of 924 with Qwen3.8-Flash-Next); the only pair without Gemma made errors (2 of 814); Gemma-4-31B-IT is the per-dollar leader and accepts the most forms; Qwen3.8-Flash-Next agrees most with the official capture, at about fifteen times Gemma's price (agreement with the capture is not accuracy on the paper).
| model | n | field agreement with the capture | accepted forms | accepted-field errors | cost per 1,000 forms | mean latency |
|---|---|---|---|---|---|---|
| Qwen3.8-Flash-Next | 128 | 97.55% | 17 | 0 of 374 | $2.11 | 119.9 s |
| Gemma-4-31B-IT (300 run) | 300 | 96.58% | 55 | 2 of 1210 | $0.14 | 87.0 s |
| Qwen3.8-27B (300 run) | 300 | 96.58% | 31 | 1 of 682 | $0.64 | 241.0 s |
| DeepSeek-V4.1-Flash | 2 | halted, not compared: deviation 2: the endpoint billed 21 requests ($0.105, about 4,200 output tokens each) and returned 2 answers; every other call ran past 300 s and then 900 s with no reply (the model was at its concurrency limit of 16) | ||||
| DeepSeek-V4-Flash-Vision-Exp | not compatible: reasoning used all 6,000 output tokens; no JSON answer | |||||
| MiMo-V2.6-Flash | not compatible: reasoning used all 6,000 output tokens; no JSON answer | |||||
| MiniCPM-V-4.7-1B | not compatible: accepts at most 4 images per request; ours has 7 (page + 6 tiles) | |||||
| MiniCPM-V-4.7-35B-A3B | not compatible: the provider answered HTTP 503 at the first 4 probes; probe 5 (2026-10-16 08:18 UTC) answered that it accepts at most 4 images per request; ours has 7 (page + 6 tiles) | |||||
The best two-reader pairs, the budget rule, and sources
Best two-reader pairs
| pair | n | accepted forms | accepted-field errors |
|---|---|---|---|
| Gemma-4-31B-IT + Qwen3.8-27B | 300 | 89 (29.7%) | 0 of 1958 |
| Gemma-4-31B-IT + Qwen3.8-Flash-Next | 128 | 42 (32.8%) | 0 of 924 |
| Qwen3.8-27B + Qwen3.8-Flash-Next | 128 | 37 (28.9%) | 2 of 814 |
A model with n < 300 read the first n forms of a fixed, capture-stratified shuffled order (pre-registered budget rule). Two readers: all 23 digit values agree, every digit read, words equal digits where read, rows sum to TOTAL. Disputes on accepted forms not already settled were decided by the certified count where it applies, else by an AI adjudicator on the crop.
sourceresults/calls_*.jsonl (last read per form), results/bakeoff_plan.json, results/adjudication/verdicts*.json; app/data/bakeoff_300.json and results/bakeoff_300.md by scripts/bakeoff.py report, recomputed by make evalLimitations I measured
The arithmetic catches any single misread; only an error that keeps every identity true passes. Each limit below is measured.
The two measured costs of the gate, and what the arithmetic cannot catch
The row-label check costs looks
The row-label check routed 86 forms; on 68 of them the read matched the paper on every field, including all 15 routed for a label alone. Each false alarm costs a person one look at a form that was read right; the check exists because a shifted row would otherwise keep the arithmetic true.
One read is not two independent reads
In one call the model can harmonise words and digits, so one read is not two independent reads: on 010469C0400 it read Unused ballots as 239 in digits and 239 in words; the paper says 234. The fix is separate reads or a second reader. Here the field (unused ballots) sits in no identity, so the gate accepted the form; it is one of the 2 wrong fields on accepted forms.
What the arithmetic can and cannot catch. Any single misread is caught, by words = digits where both are written or by a row sum or section identity; only an error that keeps every identity true passes (a compensating pair inside one sum, a misread of unused ballots, the one field in no identity, or words and digits harmonised in one call), and every wrong field on an accepted form (2 for Gemma, 1 for Qwen) is unused ballots; separate reads, a second reader and the v2 rule close it (report, section 5).
Measured ways through the frozen gate (Gemma, unused ballots): harmonised in one call (239/239 for 234) on 010469C0400; blank words (300 for 379) on 212668C0300; digit insertion (3114 for 314) on 070212B0100. The v2 rule blocks the blank-words case and the digit insertion; only a second reader removes the harmonised read.
The failure case, in full
The arithmetic gate has a blind spot: an error that keeps the arithmetic true.
Silent column shift on a rainfall ledger
Read as one image, Gemma-4-31B-IT put Balcombe Gables' 1887 values under 1886, and so on along the row. Every shifted column still sums to its total, so the checksum accepted wrong cells: on that reader, 26 of 870 accepted cells were wrong (4,915 cells read, 79.2% right overall). Zoomed tiles removed it (0 of 3,976 accepted cells wrong; spike, 40 sheets), but tiling is a mitigation, not a proof.
What I built because of it: on the tally sheet the reader must report the printed label it sees on every row, and the gate rejects a row whose label is not the one expected at that position, so a shifted or doubled row cannot pass. Its cost is measured above.
Sources: data/pilot/ledger-rescue/scores.json (models.gemma: one image per sheet, no tiles); docs/sources/ledger-rescue-pilot.md §4.
The safeguard: a person sees everything the paper cannot settle
Nothing is ever corrected silently. A form is accepted only when every identity the paper carries holds; everything else goes to the review desk with the failing field named and its crop, and a person types one value. If the paper itself is inconsistent, the person escalates it with a note. Review desk now: 344 routed forms, 0 handled.
Privacy and framing
Privacy is applied before anything else: the page is located by its corner marks and the column with officials' names and signatures is blacked out before the image is stored, sent to the model, or shown here. A page that cannot be located is not stored or sent at all; it goes to a person.
Framing: these are clerical capture checks on a settled 2024 count; the certified count is shown wherever it covers a field, and no party is compared with another and nothing is totalled across forms.
Measured, not promised
The random 300's four headline figures as cards, each with its confirmation, caveat and source.
Status of each tier, and how "wrong" was checked
The 30% tier is a secondary analysis, defined (Amendment 2) after the one-reader result was seen and before the second reader ran; it uses the lighter gate (no section checks). Wrong is judged against the official capture; every disagreement checked on the photo; fields where the model and the capture agree were not individually checked.Who judged the 52; recall
Of the 52: 22 confirmed by the certified count, 30 judged from the photo by the AI adjudicator (the builder's model, which could see both values). The multiple between the two rates is not a recall estimate.289 of 300 pages located and read (11 went to a person before any model call); 6,358 fields compared; the model agreed with the official capture on 95.8% of them. With two readers (strict mode): 89 forms, 0 wrong fields in 1,958. Recall on the capture errors the certified count reveals, Colima (pre-registered, a person's blind check): 27 of 28 caught, 96% (Wilson 95% 82-99%). One state, certified-detectable errors only; not total recall.
The cost of the problem
From INE's own 2024 files. Clerical only: no party, no totals.
On the 52,167 polling stations that were not recounted, INE's two official records of the same paper, the preliminary capture and the certified count, disagree on at least one vote field in 3,382 (6.5%). A difference says two captures disagree, not which one is right; the photo does. On my 300, the photo sided with the certified count on 22 of the 31 it covered.
The preliminary count, row sums and illegible fields, with sources
The preliminary count is preliminary by design; the certified count is the official result. 19.2% (26,336 of 137,196) of fully captured national forms fail their own row sum in the official capture. The official capture recorded 28,607 fields as "Ilegible" on 6,009 actas.
The problem: INE's two official captures of the same paper disagree on 6.5% of the polling stations that were not recounted, and 19.2% of captured forms fail their own row sum. The gap: the mandated audit checks the software, not the keyed values. The appetite: INE tried to buy an automated first capture in 2024 (an MXN 9.5M draft line, unspent), set an 80% bar that no entrant met, and its advisers asked for a pilot.
Who pays, and what runs on AMD
The regulated step the product fits, the buyer, the proposed price, and the measured compute behind it.
Institutes already tried to buy machine reading
The regulated step, the buyer's own figures, the price lines and the market, with sources
The PREP rules require a second capture and a comparison for every acta (numeral 33) and a cotejo. Two Hands checks a finished capture against the photo, field by field: it accepts what the paper's arithmetic confirms and sends the rest to a person, with the photo.
Sources: PTO 2023-2024, numeral 33; Anexo 13; my reading. The second capture costs $0.14 of AMD compute per 1,000 forms. $1 per sheet audited (proposed) · request an audit
- INE put MXN 9.5M in its 2024 draft budget for an automated first capture service (PTO numeral 30), a different step from my check, and bought none (last line). (INE report, p. 4)
- IPN quoted MXN 19.9M for the service. (INE report, p. 4)
- The acceptance bar was 80% agreement on words and digits. (INE report, p. 5)
- The best entrant reached 75%; INE declined it as untested in a real election, and its advisers (COTAPREP) recommended a pilot. (INE report, pp. 5, 10)
Two Hands is an automated capture with a referee. For 2027 I offer an independent check of a finished capture, which needs no rule change; the capture inside the loop is the pilot COTAPREP requested, offered as a pilot on 2024's own forms. Free sample: Colima, the whole state, 982 of 1,017 presidential sheets read on AMD for $0.14, field-level report.
Who pays in 2027: the PREP's outside auditor or its contracted operator, for an independent check of a finished capture, field by field against the photo. It needs no rule change: it is an outside check, which is what I measured. A model as the regulated second capture (PTO numeral 33) needs the institute's governing body to approve it after INE's opinion (RE art. 339); that is the longer-term path, not the 2027 product. Which form: state institutes (OPLEs) process local actas (governor, local deputies, municipalities). The presidential forms I measured (and the Senate forms I read) are federal, processed by INE. My local evidence is the Baja California Sur head-to-head on local actas (PROTOCOL_IEEBCS.md; result in `results/ieebcs_head_to_head.md`: Gemma matched the published values on 91.58% of fields, against Document AI's 62.84% match with the manual capture).
On that metric as I read it, Gemma's existing reads of my pre-registered 300 agree with the official capture in words and digits on 83.5% of fields (5,508 of 6,600; failed reads and blank or illegible captures count against me).
INE's 2024 acceptance metric as I read it from the report, computed on my existing reads after they were made; the definition was committed before computation; not the same test set or conditions as INE's trial.
Beside it, the result that decides acceptance: 0 wrong of 1,958 accepted fields (two readers, the paper's sums as referee), judged against the official capture; every disagreement checked on the photo; fields where the model and the capture agree were not individually checked.
1 disputed field in 5 is a confirmed capture error (52 of 267): the second capture finds what the first one keyed wrong, with the photo. Auditors check the count's system; nobody checks the captured numbers against the paper, because by hand it does not pay.
- Morelos paid MXN 26.6M for its 2024 PREP: 7,802 actas expected, 110 capture-and-verification posts, and an MXN 1.5M outside audit of the system, which by rule checks the software, not the keyed values against the paper. I check every value for $1 per acta, about 9.5% of Morelos's audit line and 0.5% of its PREP cost per acta (MXN 3,409, ~$185). (IMPEPAC, Informe Final PREP 23-24 v2.0, p. 56, https://impepac.mx/wp-content/uploads/2024/07/Informe%20Final%20PREP_23-24_V_2.0.pdf; audit scope: RE art. 347 numeral 1; INE's 2024 audit (UAM-I), PDF p. 7, https://ine.mx/wp-content/uploads/2024/06/2024-PREP-InformeFinalAuditoriav1.pdf)
- Baja California Sur bought an AI first capture by direct award (Google Document AI, MXN 93,834.49); it matched the human capture on 2.88% of actas and 62.84% of fields. A machine already keys; the question is who referees it. (IEEBCS, Informe final del PREP 2023-2024, pp. 19 and 31, https://www.ieebcs.org.mx/documentos/acuerdos/INFORME_FINAL_PREP_PLE_2023-2024.pdf)
- Every state institute decides whether to run its PREP alone or with a third party at least six months before election day: for 6 June 2027, by about 6 December 2026. Guerrero has already decided: in-house, "con acompañamiento de un ente especializado". (Anexo 13 numeral 33 punto 7, as cited in IEPC Guerrero Acuerdo 057/SO/16-07-2026, considerando XI and XXVI-XXVII, https://www.iepcgro.mx/principal/uploads/gaceta/2026/7ord/acuerdo057.pdf)
- The 2027 buyer is the outside auditor or the contracted PREP operator, paid by the state institute (OPLE). At least 13 of the 17 outsourced 2024 state PREPs went to three firms: Informática Electoral S.C. (at least 8 states), Grupo Proisi (4) and PoderNet (1). (INE UTSI, Anexo 3 'Terceros que auxiliarán a los OPL', Feb 2024, https://repositoriodocumental.ine.mx/xmlui/bitstream/handle/123456789/166144/ccoe-1so-23-02-2024-p19-a3.pdf; Morelos: IMPEPAC monthly PREP report, March 2024, p. 19; Campeche: Por Esto, 12 Mar 2024 (press))
Commercial cloud OCR as the first capture in the 2024 Baja California Sur PREP: 14,501 of 23,077 fields matched the manual capture, 62.84% (IEEBCS final report, p. 19). Open Gemma-4-31B-IT on AMD (Token Factory, Gemma-4-31B-IT), on a pre-registered sample of 300 of the same state's published actas, against the same published values: 91.58% of all fields (3,317 of 3,622); 93.25% on the 294 pages the locator accepted.
Same images; reference and pipeline differ (their raw manual capture vs. the published values; election night vs. offline); their per-field output isn't published, so it can't be re-scored. Details on Results. The head-to-head
Anchor: INE's own line was MXN 9.5M for ~170,000 actas, about MXN 56 (~$3) per acta for a first capture alone. Costs: AMD compute $0.00014 per form (measured); review labour for routed fields about $0.09 to $0.13 per form (estimate: 20 s per disputed crop, 0.92 crops per form measured, $18 to $25 an hour); plus hosting and sales. Examples: Morelos, 7,802 forms: about $7,800 (MXN 143k), under the lowest federal direct-award ceiling; the largest state (Estado de México), 20,908 forms: about $20,900 (MXN 384k), over the lowest federal direct-award ceiling, under the highest; the federal count, 169,005 forms: about $169,000 (MXN 3.1M), over every federal direct-award ceiling: a tender; INE's own line was MXN 9.5M. Self-serve (CLI / MCP, you review your own disputes): $0.10 per form. FX MXN 18.3835 per USD (ECB, 2026-10-16).
Give me your keyed data and the scans. You get the 4% of fields to look at, each with its photo. A person checks 1 field in 24 instead of every field.
How big (my estimate): about 170,000 federal actas (169,005 presidential sheets in 2024, one per polling station) plus the local actas of the 32 local processes, two to three per polling station where a state elects two or three local offices (Morelos 2024: 7,802 local actas for three offices), so roughly 500,000 to 700,000 actas in a concurrent year. Mexico's PREPs are the beachhead; the same field-level check applies wherever keyed values must match paper. (PREP 2024 CSV (169,005 presidential sheets); IMPEPAC Informe Final PREP 23-24, pp. 3-4 (Morelos local actas); INE Central Electoral 2026-07-30 (32 concurrent local processes). The 2-3 local actas per polling station is my estimate.)
Next markets, not measured:
- Health facility monthly reports (HMIS / DHIS2): WHO's Data Quality Review recounts the paper source documents against what was keyed into the national database, and DHIS2 is the national health data system in 70+ countries (dhis2.org/health/hmis); the monthly forms carry their own totals (Kenya MOH 711A: new + re-visits = total). (WHO, Data Quality Review Module 3 (2020), https://cdn.who.int/media/docs/default-source/data-quality-pages/2021_dqa_module-3_site-assessment-framework.pdf; https://dhis2.org/about/; MOH 711A, https://tciurbanhealth.org/wp-content/uploads/2017/06/M2_-_MOH_711A_Facility_integrated_Form-3.pdf)
- US mortgage post-closing QC: Fannie Mae's Selling Guide makes lenders re-check at least 10% of the loans they close (or a statistical sample) every month, plus targeted selections, against the source documents; 4.4 million closed-end originations in 2023. (Fannie Mae Selling Guide D1-3-01 and D1-3-02 (04/01/2026), https://selling-guide.fanniemae.com/sel/d1-3-01/lender-post-closing-quality-control-review-process; CFPB, https://www.consumerfinance.gov/data-research/hmda/summary-of-2023-data-on-mortgage-lending/)
- Clinical-trial source data verification: a 7,000-trial analysis found it corrects 1.1% of site-entered data, while monitoring and verification take 15-30% of trial costs; pointing the monitor at the fields the paper disputes is the mechanism I measured on election forms. (Medidata/TransCelerate, Clinical Leader Nov 2014, https://www.clinicalleader.com/doc/medidata-transcelerate-biopharma-inc-clinical-trial-0001; Lindblad et al., Clinical Trials 2014; 11: 205-217)
Open models on the AMD endpoint
AMD Token Factory (organisers' hosted AMD GPU endpoint, OpenAI-compatible). Every measured read went through it, and the live audit reads through it now.
Measured on Gemma-4-31B-IT on the AMD Token Factory.
reader now: Gemma-4-31B-IT on AMD Token Factory
$0.000144 per form
2,609 tokens in, 804 out
$0.000507 per form
8,739 tokens in, 1,667 out
- Input per form
- 1 masked page + zoomed tiles, one request
- Live audit
- not started yet · status
Gemma vs the other readers on AMD
Any form that checks itself
A new form type is a schema file, not code: draw the fields, write the identities, test it live.
Twelve months must add up to the year. 3,976 of 3,976 accepted cells right against the transcription by ~16,000 volunteers, 4 transcriptions per value (spike, 40 sheets). Open a ledger sheet
The identities the gate applies to the tally sheet, verbatim from its schema:
All runs
The 43-form pilot, the ledger spike, the re-reads during endpoint outages, and the live reads. Not part of any headline.
Pilot (43 hand-picked forms)
Before the pre-registered run: 43 forms chosen to be difficult, from 10 districts. Not random, so these rates do not generalise; they are here for the record.
| Reader | Forms | Accepted | Accepted fields wrong (vs capture → after eye check) | All fields right | Routed, read perfectly | USD / form | Mean s |
|---|---|---|---|---|---|---|---|
| Gemma-4-31B-IT, page + 4 tiles (spike v2) results/pilot/tally-witness/results_v2/gemma__*.json |
43 | 21 (49%) | 5 → 0 of 462 | 97.4% | 7 | $0.000118 | 49 |
| Qwen3.8-27B, page + 3 tiles (spike) results/pilot/tally-witness/results/qwen__*.json |
43 | 22 (51%) | 4 → 0 of 484 | 98.2% | 10 | $0.000507 | 85 |
| Gemma-4-31B-IT, page + 3 tiles (spike v1) results/pilot/tally-witness/results/gemma__*.json |
43 | 17 (40%) | 6 → 0 of 374 | 93.2% | 6 | $0.000102 | 55 |
| Gemma-4-31B-IT, rainfall ledgers, whole sheet + 3 zoomed strips ledger/ledger.json (spike, 40 sheets) |
40 sheets 380 year-columns |
306 cols (80.5%) | 0 of 3,976 cells (spike, 40 sheets) | 96.8% | — | $0.000110 | — |
"Routed, read perfectly": the gate sent the form to a person although every field was read right, because the paper itself is inconsistent. Pilot runs predate the row-label check.
Appendix: re-reads and endpoint outages
Not part of any headline.
During the pre-registered run, 51 of the 300 forms had a first call fail during endpoint outages (HTTP 503) and were re-read later with the same frozen prompt; the last read of each form counts (355 rows in results/calls_gemma.jsonl).
| Re-read of masked pilot forms | Forms | Fields differing from the capture | Mean s |
|---|---|---|---|
| Gemma-4-31B-IT, re-read of masked forms with the frozen prompt, attempt 1 results/verify_spike_gemma_try1.jsonl | 5 | 8 of 110 | 160 |
| Gemma-4-31B-IT, re-read of masked forms with the frozen prompt, attempt 2 results/verify_spike_gemma_try2.jsonl | 5 | 28 of 110 | 477 |
| Gemma-4-31B-IT, re-read of masked forms with the frozen prompt, attempt 3, during an endpoint outage results/verify_spike_gemma_try3_outage.jsonl | 5 | 110 of 110 | 340 |
| Qwen3.8-27B, re-read of masked forms with the frozen prompt results/verify_spike_qwen.jsonl | 2 | 2 of 44 | 451 |
The attempt made during an outage returned no usable read for any field, which is why it shows every field as differing.
Live reads made from this site: 1 forms, mean 63 s.
Evolus
The same process runs as a case on Evolus (Evolus Business Agents track); the masked page is the input, and an open model on AMD reasons over it.
Evolus event workspace: py_tr (event code AMDACT3)
The blocks, the live cases and the recorded findings
The agent "Intake clerk" runs on Gemma-4-31B-IT on the AMD Token Factory, connected in the workspace under "Your models" as an OpenAI-compatible server. Blocks: agent "Intake clerk", workflows "Review hand-off", "Record filing" and "Audit finding", AI Tool translate. Name from Evolus API: GET /api/v1/agents/{agentId} -> application.name.
In the live audit: every strong-evidence dispute the live worker finds starts one "Audit finding" run in Evolus (at most 60 a day, to protect the shared AMD key). Today: 0 of 60.
Routed cases in the workspace: Evolus workspace py_tr: 150 "Audit finding" executions of real routed fields (100 from the 300 run, 50 from Colima): 150 of 150 completed; in all 150 the Evolus Script's own recomputation of the evidence score matches mine; model reported by Evolus: own/gemma-4-31b-it (ok). Source: results/evolus/executions.jsonl.
- 060334B0100 · Ballots taken from the boxes · Routed: rows sum to TOTAL (213 vs 205); section 5 = section 7 (215 vs 205) · run e7d685ff: The paper shows 205 and two hundred five. No value was keyed. The identity section 7 = TOTAL supports the paper's value for the auditor to confirm.
- 060258C0300 · Voters on the list · Routed: Voters on the list digits 354, words 357; section 5 = section 7 (355 vs 357) · run 1c6b5cf0: The paper shows 354 and three hundred fifty-seven for Voters on the list. No value was keyed. The identity voters + representatives = section 5 supports the paper's value for the auditor to confirm.
- 060093C0100 · Ballots taken from the boxes · Routed: section 5 = section 7 (376 vs 382) · run 286733e1: The paper shows 382 and no amount in words for Ballots taken from the boxes. No value was keyed. The identity section 7 = TOTAL supports the paper's value for the auditor to confirm.
Recorded "Audit finding" cases (newest first, 21 with a drafted finding; results/evolus_audit_runs.jsonl):
- 050815B0100 · Option 07 · 2026-10-16 19:32 UTC · drafted by the Intake clerk on Gemma-4-31B-IT · run 68359545: The paper shows 175 and one hundred seventy-five. The value 75 was keyed for Option 07. The identity rows sum to TOTAL supports the paper's value for the auditor to confirm.
- 131468C0100 · TOTAL · 2026-10-16 19:32 UTC · drafted by the Intake clerk on Gemma-4-31B-IT · run 5dae9d3e: The paper shows 354 and three hundred fifty-four. The keyed value is 352. The identities rows sum to TOTAL and section 7 = TOTAL support the paper's value for the auditor to confirm.
- 094821C0200 · TOTAL · 2026-10-16 19:32 UTC · drafted by the Intake clerk on Gemma-4-31B-IT · run b862c629: The paper shows 388 and three hundred eighty-eight. The keyed value is 386. Both rows sum to TOTAL and section 7 = TOTAL support the paper's value for the auditor to confirm.
Accepted form
Starts the workflow "Record filing": a deterministic script re-checks the paper's identities inside Evolus and files the record.
Routed form
Starts "Review hand-off": the agent "Intake clerk" (an open model on the AMD Token Factory) writes the review task, the AI Tool translate turns it into Spanish, and the task reaches a person on my review desk, where "Send to Evolus" starts it for any routed form.
Audit findings and a third reader
From an audit report, each strong-evidence field opens an "Audit finding" case with a drafted finding and a score a script recomputes. An Evolus extractor reads as a third reader, gated and compared, never trusted blindly.
Each form page and the review desk show the form's Evolus run: id, steps and status. sourcedocs/EVOLUS.md; evolus/ (python -m evolus setup, python -m evolus run); results/evolus_runs.jsonl, results/evolus_audit_runs.jsonl, results/evolus/executions.jsonl
AMD status
AMD Token Factory (organisers' hosted AMD GPU endpoint, OpenAI-compatible).
No probe of the AMD endpoint in the last 15 minutes.
reader now: Gemma-4-31B-IT on AMD Token Factory
Latency and cost per model: open models on the AMD endpoint.
sourceresults/endpoint_health.jsonl (probes of the endpoint); app/health.py